
AI Infrastructure & LLMs
Large language models, AI assistants, data centres, AI chips, cooling, optical networks and the power systems behind modern artificial intelligence.
-
Google’s TPUs Are Leaving Google Cloud for Oracle’s Data Centres
Oracle will become the first hyperscale cloud outside Google to offer Google TPUs, a 2027 move that could weaken the link between custom AI chips and the cloud companies that designed them.
-
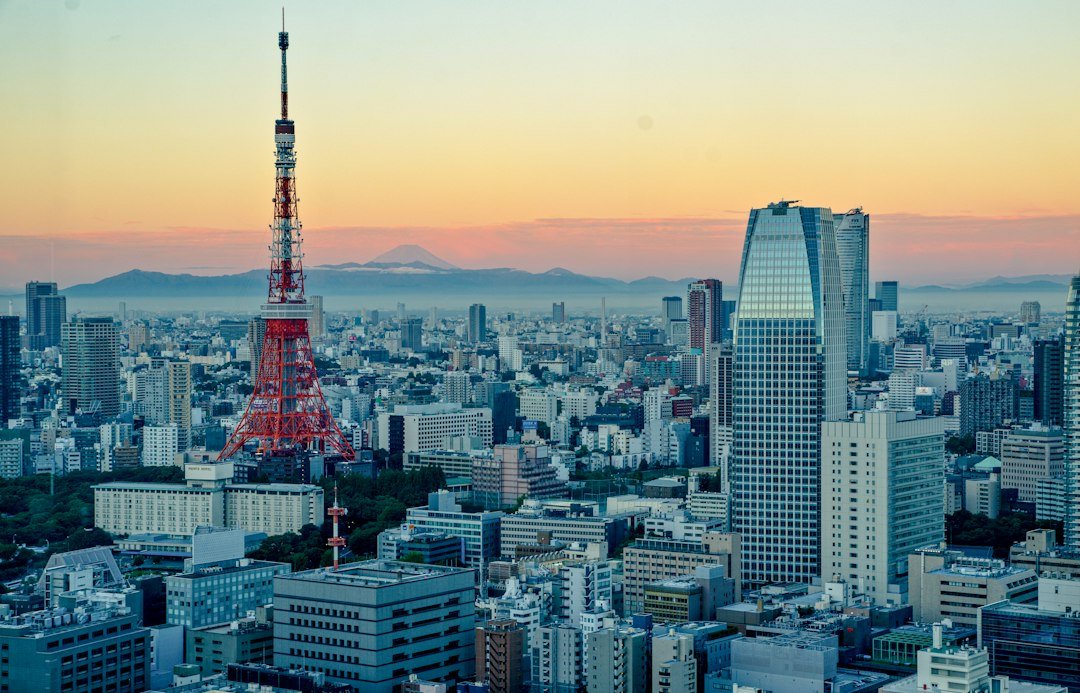
Tokyo’s ¥93 Billion Green Loan Turns Data-Centre Efficiency Into a Financing Test
STTGDC’s loan for a 70.8 MW Tokyo campus ties financing to building certification and a design PUE of 1.3 or better, making measurable efficiency part of the capital stack.
-
AMD and Intel Merge Their CPU AI Software Paths Around oneDNN
AMD will bring ZenDNN work into oneDNN, the shared PyTorch path for x86 CPU AI. The collaboration targets portability, not a guaranteed speedup.
-
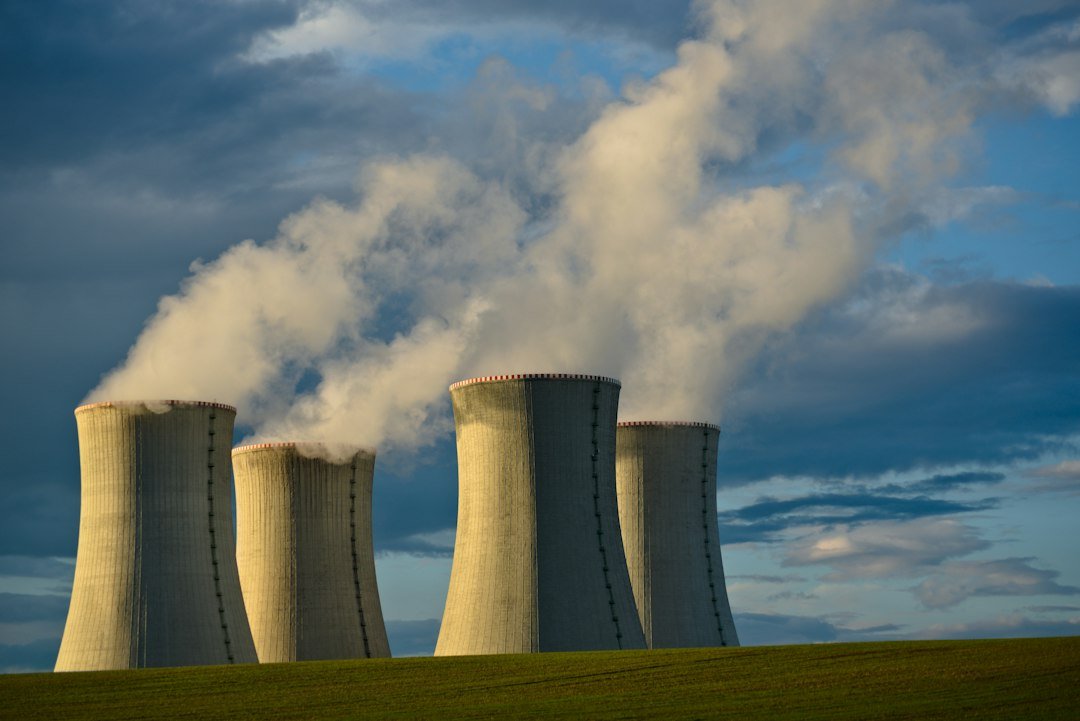
Retired Nuclear Sites Become Candidates for Germany’s AI Factories
PreussenElektra and NVIDIA will assess retired German nuclear sites for AI data centres. The proposal reuses infrastructure, not nuclear power.
-
NVIDIA’s DSX POD Moves AI Factories Onto the Assembly Line
NVIDIA says partners can factory-integrate Vera Rubin computing, networking, power and liquid cooling into modular containers. The claimed 14-day site deployment starts only after utilities and foundations are ready.
-
SpaceX’s $40 Billion Chip Lease Turns AI Hardware Into Infrastructure Debt
An Apollo-managed affiliate will buy AI chips and servers and lease them to SpaceX under a roughly $40 billion principal-payment agreement. It is equipment finance, not $40 billion of immediate revenue or delivered computing capacity.
-
Google’s A5X Plan Turns AI Scale Into a Networking Claim
Google Cloud says A5X instances built on NVIDIA Vera Rubin will become generally available in November, with Virgo networking designed for up to 80,000 GPUs at one site and 960,000 across sites. Those are architecture limits, not deployed capacity.
-
HPE’s Mixed-GPU Private Cloud Makes Scheduling the Scarce Resource
HPE Private Cloud AI can now combine H200 and RTX PRO 6000 Blackwell GPUs in one cluster, using KAI Scheduler to assign work by quotas and priorities. The update shifts attention from buying accelerators to governing who gets them.
-
Intel’s 480 GB Inference GPU Makes Memory Capacity the Main Bet
Intel’s GPU D-series targets large-model inference with unusually high memory capacity and air-cooled PCIe deployment, but independent benchmarks are still missing.
-
Vultr’s 20 MW Chennai AI Cluster Is a Sovereignty Plan, Not Live Capacity
Vultr plans to open a Chennai cloud region with an initial 20 MW AMD accelerator cluster and a 2027 expansion path. The announcement is a commercial capacity plan, not evidence that the hardware is already serving customers.
-
The IEA Finds Data-Centre Policy Is Becoming Power-System Policy
An International Energy Agency review finds that governments are rapidly rewriting rules for data centres, electricity connections and AI infrastructure. The report maps 134 policies across jurisdictions representing most global data-centre capacity.
-
Meta Makes AMD Training Competitive by Rewriting the Software Around the Chip
A Meta–AMD preprint reports production recommendation-model training on tens of thousands of MI350X accelerators at roughly the throughput of Meta’s established Nvidia B200 baseline. The result depends on extensive model, kernel and systems co-design.